Home
>
PDF Editor
>
Six Insights Behind Why We Built PDNob Features the Way We Did
Six Insights Behind Why We Built PDNob Features the Way We Did
A PDF may look simple at first glance: open it, read it, edit it, convert it, share it. But anyone who works with complex PDFs knows that things are rarely that simple. A scanned contract may come back skewed, shadowed, or with faded text. A research paper may use multiple columns, mixed fonts, footnotes, and tight layouts. A technical drawing may contain layers, vector objects, clipped images, and annotations. And once you start editing, even a small change can ripple through fonts, object positions, comments, or the surrounding layout. That's why we observe and investigate, test multiple times, and dedicatedly design every detail.
We've finally made fine-tuned improvement improvements in six areas where PDNob has rebuilt the PDF experience to handle that complexity: OCR pre-processing, reading-mode editing, translation, large-document rendering, annotation tracking, and AI-powered tool calling. We spend a lot of time on details you may or may not consciously notice—but which cause unnecessary wasted time when something goes wrong. The goal is simple: make complex PDF work more predictable, more efficient, and easier to control.

Part 1. Better OCR Starts Before Recognition
OCR Pre-processing for Any Document
Why Scanned PDFs Always Look Messier Than They Should
Sometimes you open a scanned contract on your phone, hit OCR, and watch the result come out --- italic English has turned into garbled characters, dates are in the wrong format, a phone number is one digit short. The recognition engine is often blamed, but most of the time the source image is the problem: a page scanned at an angle, a receipt with shadows, an old book with worn print, a faxed page with speckles.
Pass that raw image to an OCR engine and the errors begin before recognition even starts. That is why we treat pre-processing as a separate, tunable step.
How We Rebuild the OCR Pipeline for Messy Scans
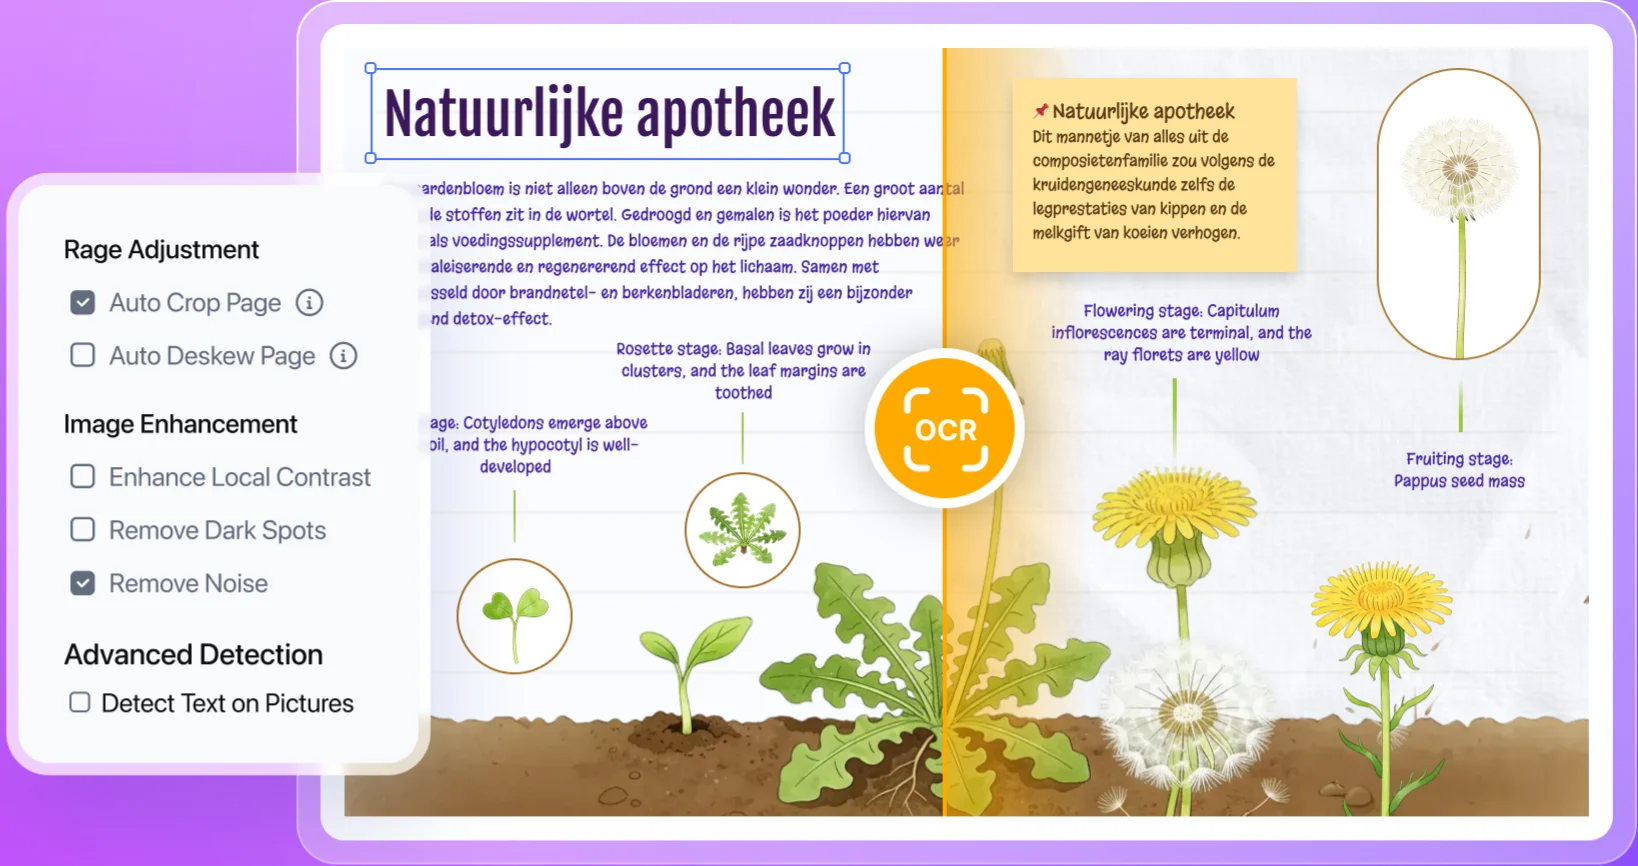
We spent months iterating on the OCR pipeline after working alongside legal teams digitizing contracts, archivists restoring old journals, and field workers pulling text from phone photos of receipts. What we kept hearing was the same: the recognition model is often blamed, but the source image is the real problem. So we rebuilt pre-processing from the ground up --- five options you can turn on or off independently, depending on what the document actually needs.
-
Auto Crop Page: Detects and trims borders, margins, and empty edges so only the document body is fed to the recognizer.
-
Auto Deskew Page: Rotates tilted pages back to vertical, useful for books photographed on a desk or pages scanned in batches.

-
Enhance Local Contrast: Boosts local contrast on faded, washed-out, or low-exposure scans so faint text becomes legible.
-
Remove Dark Spots: Clears stray black dots and artifacts from old photocopies and faxed pages.
-
Remove Noise: Smooths grainy backgrounds from low-light mobile photos.
-
Detect Text on Pictures: Independent control over text-in-image detection, so you can extract just the body text or skip captions inside figures.

In an internal benchmark on a mixed Chinese-English catalog page, PDNob reached a 93.7% recognition rate with a 10-second turnaround.
Where PDNob OCR Has Its Advantage
Most editors take a one-size-fits-all approach: the engine receives the raw scan and recognition begins immediately. PDFelement, Foxit, UPDF, and WPS focus their engineering on the recognition side, so pre-processing tends to be lighter and the result depends more on input quality. PDNob now can offer you pre-processing as an independent, tunable stage.
 Please swipe to view
How This Helps Your OCR Workflow
The important part is not simply having OCR. It is making the document easier for OCR with auto pre-processing for higher recognition accuracy in the first place. Instead of treating every scanned document in exactly the same way, we let the OCR workflow adapt to the condition of the source document. This is useful when you need to:
- Extract text from photographed contracts and signed agreements captured on mobile devices
- Digitize old books and journal articles where pages may be skewed or faded
- Pull text from low-light receipts, invoices, and expense reports
- Convert multi-format research papers with mixed scans, equations, and figures


Part 2. Editing That Holds Together on Complex Documents
Six refinements on editing features keep PDNob ahead on the small edits that add up to hours saved across long documents --- paragraph logic, selection boxes, layering, font handling, and format retention.
Paragraph Editing in Reading Mode
Why a Simple Typo Fix Even Take Five Clicks
If you are halfway through a 60-page contract and notice a typo on page 12. In most PDF editors, that means leaving reading view, switching into edit mode, hunting for the cursor, fixing the typo, then switching back. Five transitions for one word. Across a long document those transitions add up.
How We Removed the Edit Mode Switch
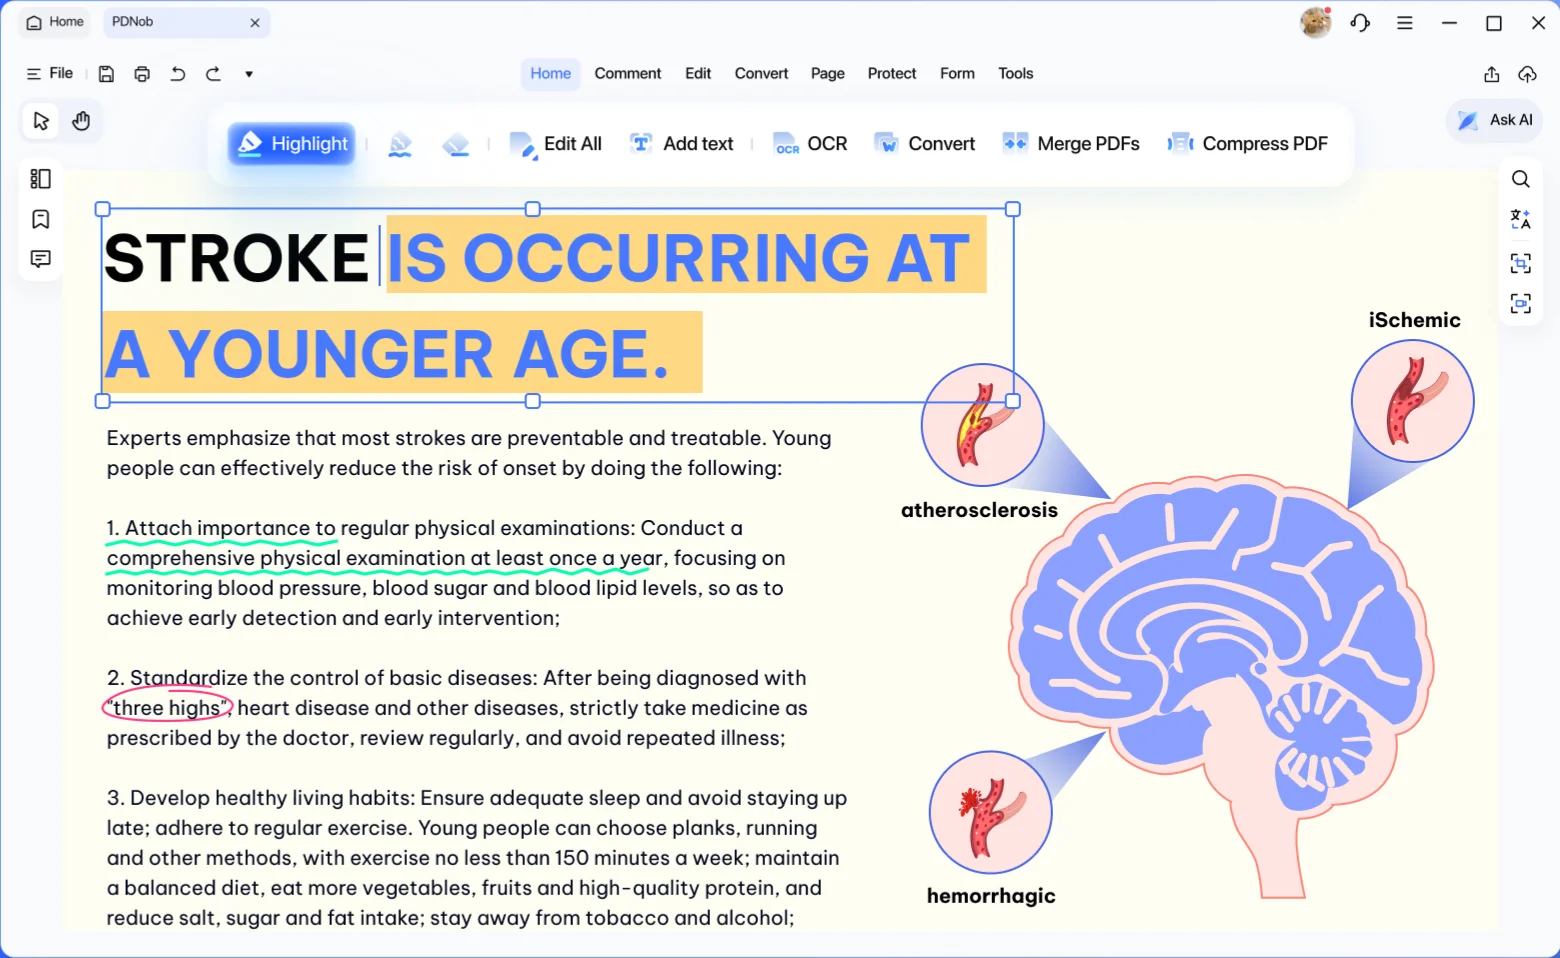
We redesigned the read-then-edit flow after watching legal reviewers and editors lose time to mode-switching across long documents --- five transitions for one word is too many. We made click-to-edit the default. Click any text in reading view, the cursor lands exactly where you clicked, and you start typing. Bold, italic, font, and size are preserved on the original style, so the edit blends in without reformatting.
- Click-to-Edit Anywhere: Click any text to start editing --- no mode switch, no extra toolbar step.
- Cursor Where You Click: The insertion point appears precisely at the click location, not a paragraph above or below.
- Style Preservation: Bold, italic, font family, and size are retained on the original run.
What Other Editors Ask You to Click Through
In most PDF editors, fixing a typo means leaving reading view, switching into edit mode, hunting for the cursor, fixing the typo, then switching back. Some tools now let the cursor land in reading view, but the edit still needs a toolbar confirmation. PDNob now can offer you direct edit from reading view with no toolbar step in between.
Please swipe to view
How This Design Save Your Effort
The idea is simple: if you are already looking at the text you want to change, you should not have to leave the reading experience just to edit it. That means less time fighting with selection handles and more time working with the actual document. This is useful when:
- Fixing typos and date errors in contracts while reading through them
- Updating figures and quoted statistics in draft reports without losing formatting
- Cleaning up OCR output in reading view before passing the document downstream
Stable Selection Box for Complex Objects
Why Selecting an Irregular Image Can Be Tricky Elsewhere
You might have experienced this: you are working on a design-heavy PDF and want to grab a rotated image or an irregularly cropped shape. The selection box appears to cover only half of it, or jumps off the object when you rotate it. You spend more time wrestling with selection handles than actually moving things around.
How We Stabilized Selection on Irregular Objects
To solve this problem, we reworked the selection calculation. In the design and editorial workflows we support, the selection step is one of the most common silent time sinks. Selecting an object in a PDF sounds simple --- until the object is rotated, clipped, irregular, or built from a custom path. We now wrap irregular objects, clipped images, and custom paths into a clean bounding box that stays aligned through rotate, scale, and skew.
- Irregular Path Support: Cropped images and custom shapes get accurate, fully-wrapped selection boxes.
- Stable Under Manipulation: The selection box stays aligned during rotate, scale, and skew operations.
- Consistent Across Object Types: Images, vector paths, shapes, and text boxes all behave the same.
How Each Editor Handles the Selection Box
Different editors handle irregular shapes differently. PDFelement partially wraps some objects. Foxit and WPS can show a selection box that drifts off the object during rotate or scale. PDNob now can offer you a selection calculation that stays consistent across object types.
Please swipe to view
How Selection Stability Smooth Your Workflow
These details may not appear on a feature checklist, but they can important when working with complicated designing PDFs. This is useful when:
- Selecting cropped images for movement or resizing inside design PDFs
- Manipulating custom shapes and irregular paths without losing the box
- Rotating watermarks and badges without the selection drifting off
Precise Layer and Z-Order Adjustment
Why Object Stacking Matters When a Watermark Sits Over Text
You move a watermark, a logo, or a background image and the layering shifts in a way you did not expect --- the watermark ends up hiding the title, or a text edit silently pushes the object to a different layer. Getting the order right often takes multiple attempts.
How We Built Document-Level Layer Control
We rebuilt document-level stacking after watching design and report teams waste time getting the order right --- moving a watermark should not push the title underneath into a different layer. We now give you document-level control over object stacking order. Move any object to the very front or very back of the stack, and the relative position survives text edits. For design-heavy documents imported from other tools, nested groups keep their hierarchy intact.
- True Global Z-Order: Move any object to the top or bottom of the stack, regardless of nesting.
- Layer-Aware Text Editing: Text edits keep the object's relative position with other layers intact.
- Nested Group Support: Complex groups with internal layers preserve their hierarchy.
Z-Order at the Object Level vs. the Document Level
Most editors offer some layer control, but the depth varies. Foxit supports global adjustment, though relative layer position can shift during text edits. PDFelement and WPS cover basic layer moves, without a document-level view. PDNob now can offer you the whole-document stacking order as one workspace.
Please swipe to view
Use Cases
These details may not appear on a feature checklist, but they become important when working with complicated PDFs. This is useful when:
- Adjusting the overlap between watermarks, logos, and background graphics
- Stacking images behind text or shapes in design drafts
- Organizing multi-layer PDFs imported from design software
Smarter Paragraph Recognition in Complex Layouts
Why Editing Two-Column Layouts Often Breaks
Let's say you open a two-column academic paper to fix one sentence in the abstract. After the edit, the layout shifts: a paragraph from the right column jumps to the left, headings no longer line up, and a footnote detaches from the body it was meant to anchor. What looked like a simple edit quietly restructures the page.
How We Retrained the Paragraph Model for Complex Layouts
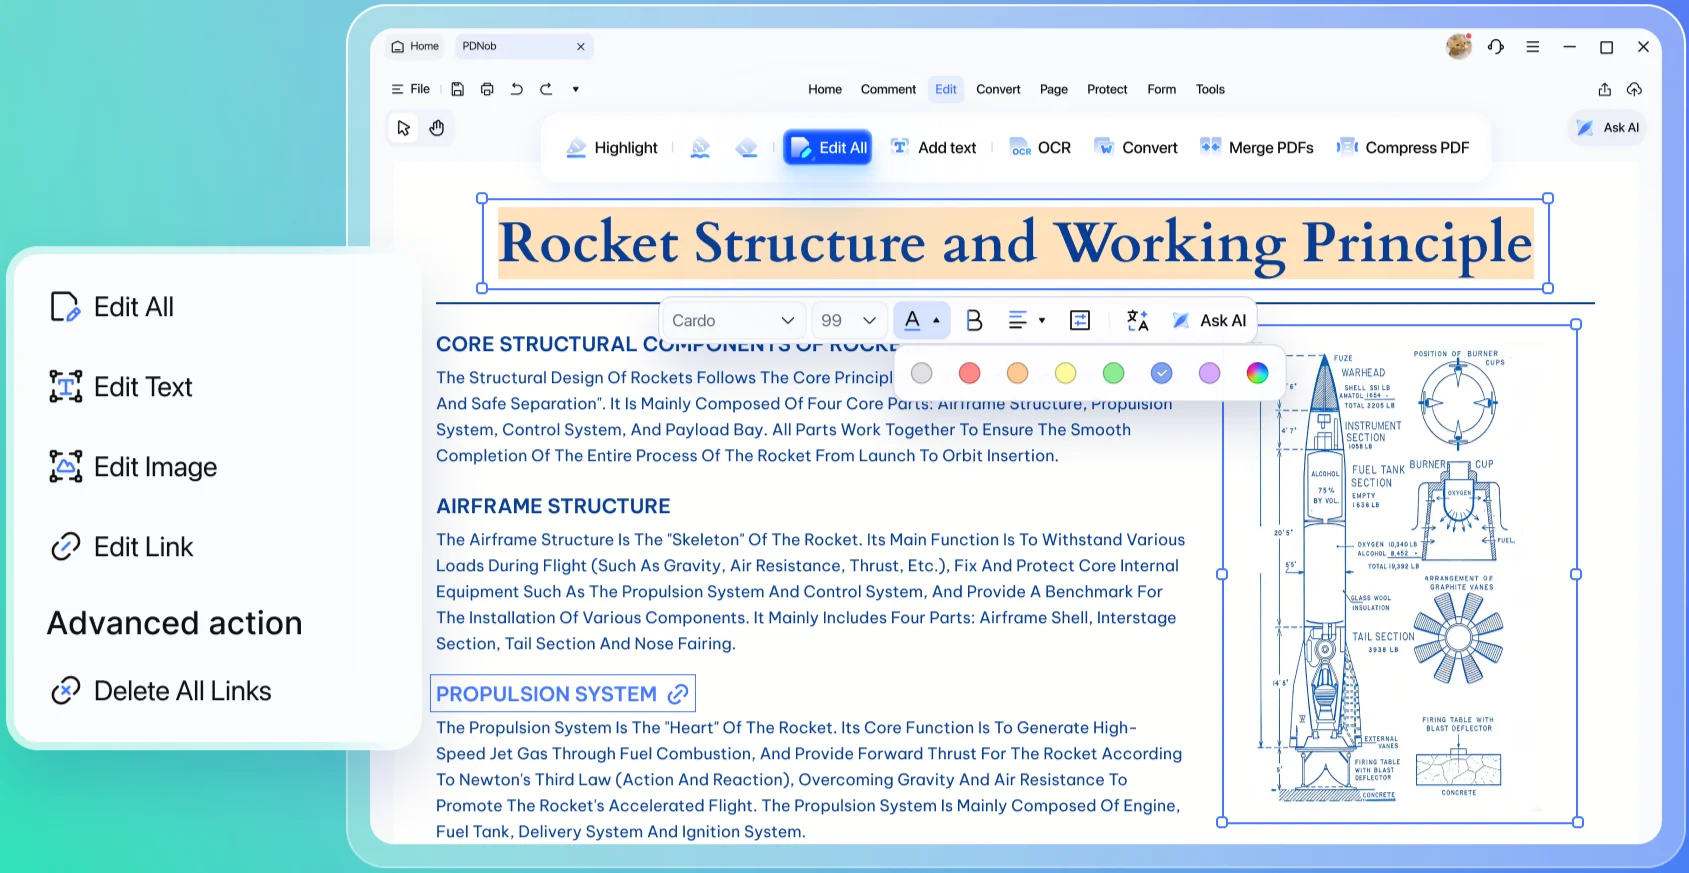
We retrained the paragraph model on complex layouts after watching a single two-column edit quietly restructure an entire academic page. A PDF page can visually contain several columns, headings, footnotes, and mixed formatting, while the underlying text structure is far less obvious. When the underlying structure is misread, editing breaks the layout. On a 309-page internal test set, the F1-Core score improved by 1.55% over the previous version --- and in a cross-tool benchmark of Adobe, Foxit, UPDF, and PDFelement, PDNob ranked #1 with 89.88% F1 on complex layouts.
- Multi-Column Detection: Recognizes paragraphs across columns with precision.
- Mixed-Format Sections: Identifies paragraph boundaries in mixed-format pages.
- Improved F1 Score: 1.55% higher F1-Core over the previous version on a 309-page test set.
- Top of Class on Complex Layouts: 89.88% F1 in our test across the five tools compared here.
Where Paragraph Reading Becomes the Bottleneck
How well an editor preserves complex layouts depends a lot on how well it reads the structure underneath. Adobe, PDFelement, UPDF, and Foxit each handle standard documents well, but on the multi-column, mixed-format documents we tested, the underlying paragraph reading is what separates them. PDNob now can offer you paragraph recognition trained specifically on the multi-column, mixed-format case.
Please swipe to view
Where It Fits Into Your Work
The value of this optimization is straightforward: setting the order once should be enough. The stacking between your watermarks, logos, and background graphics stays where you placed it --- no need to redo the layering after every text edit. This is useful when:
- Editing multi-column academic papers without breaking paragraph boundaries
- Restructuring mixed-format reports where sections use different styles
- Working with book layouts that mix headers, body text, and footnotes
Format-Preserving Copy Across Apps
Where Copying a Heading Formatting Can be Problematic
In other PDF editors, if you highlight a bold heading in a PDF, copy it, paste it into a Word or WPS document --- and the bold is gone. Same with numbered lists: paste them in and the numbers reset to plain text. The words came across; the structure did not.
How We Kept Formatting Through Copy-Paste
We focused on copy-paste fidelity after noticing that editors and report writers usually redo the same formatting over and over after every paste. Copying text from a PDF into another application should not mean rebuilding the formatting from scratch. We now preserve formatting attributes --- font, size, bold, italic, numbered lists --- when text moves between the PDF editor and common office applications.
- High-Fidelity Text Copy: Preserve bold, italic, and font style when copying text.
- Office App Compatibility: Works with Word, WPS, and other common editors.
- No Reformatting Loop: Avoid re-applying formatting after pasting.
What Survives the Copy-Paste Round Trip
Different tools handle copy-paste fidelity differently. WPS has historically retained formatting. Adobe, PDFelement, UPDF, and Foxit have varied in how consistently bold, italic, and lists survive the round trip. PDNob now can offer you consistent formatting survival across the copy-paste round trip.
Please swipe to view
How This Save Repeated Work
The goal of this improvement is not simply to copy the words. It is to preserve the structure and formatting that make those words useful. This is useful when:
- Moving quotes into Word reports with bold and italic intact
- Transferring numbered lists into WPS documents without losing numbering
- Copying styled headings between office apps during report assembly
- Adding research notes from PDF sources while keeping source formatting
Faster and More Accurate Font Matching
How Font Replacement Quietly Complicates Long Documents Edtiting
You open a 300-page manual and start inserting new sections. Halfway through, you notice the new paragraphs are in a slightly different font from the original --- the engine quietly substituted a font it could not match. By the time you spot it, the document looks inconsistent across chapters.
How We Rebuilt the Font Matching Engine
We rebuilt the font matching engine because nothing breaks long-document consistency faster than a quiet font swap halfway through a chapter. Fonts are the kind of detail that becomes obvious only when something goes wrong. Our engine now handles a wider range of font variations --- including bold and italic styles --- while reducing the surprise font swaps. In an internal test involving an insertion of more than 10,000 characters, the operation took approximately 5 to 6 seconds under the tested conditions.
- Bold and Italic Variants: Better support for additional font weights and styles.
- Reduced Substitutions: Fewer cases where the engine swaps fonts mid-document.
- Faster Large Inserts: ~5 to 6 seconds for 10,000+ character inserts under the tested conditions.
Why Font Handling Shows Only on Long Inserts
Font matching is one of those areas where the gap only shows on long documents. In our test, WPS came in around 9 seconds, PDFelement 25+ seconds, and UPDF around 1 to 2 minutes for the same 10,000+ character insert. PDNob now can offer you faster font matching that keeps the original typography intact on long inserts.
Please swipe to view
How It Save Your Time in Editing
That enhancement means consistent font handling can make a significant difference to the final result on long document revisions. This is useful when:
- Inserting long passages into thesis drafts without font replacement
- Adding new chapters to existing books while keeping the original typography
- Batch-updating manuals where consistent fonts matter for brand identity
Part 3. Translate PDFs Without Breaking the Original Layout
Two translation modes cover the cases where machine translation usually breaks a PDF --- bilingual reading for spot checks, and full-document translation for finished output.
Side-by-Side Bilingual Reading
Why Reading a Foreign PDF Takes Two Browser Tabs
It's a common scene for most students or researchers: you are working through a 30-page English research paper. To check a term, you highlight a sentence, copy it, switch to a browser tab, paste into a translation tool, read the result, switch back, and try to remember where you were in the paper. By the time you finish the abstract, you have lost your reading flow.
How We Brought Bilingual View Translation for the Reader
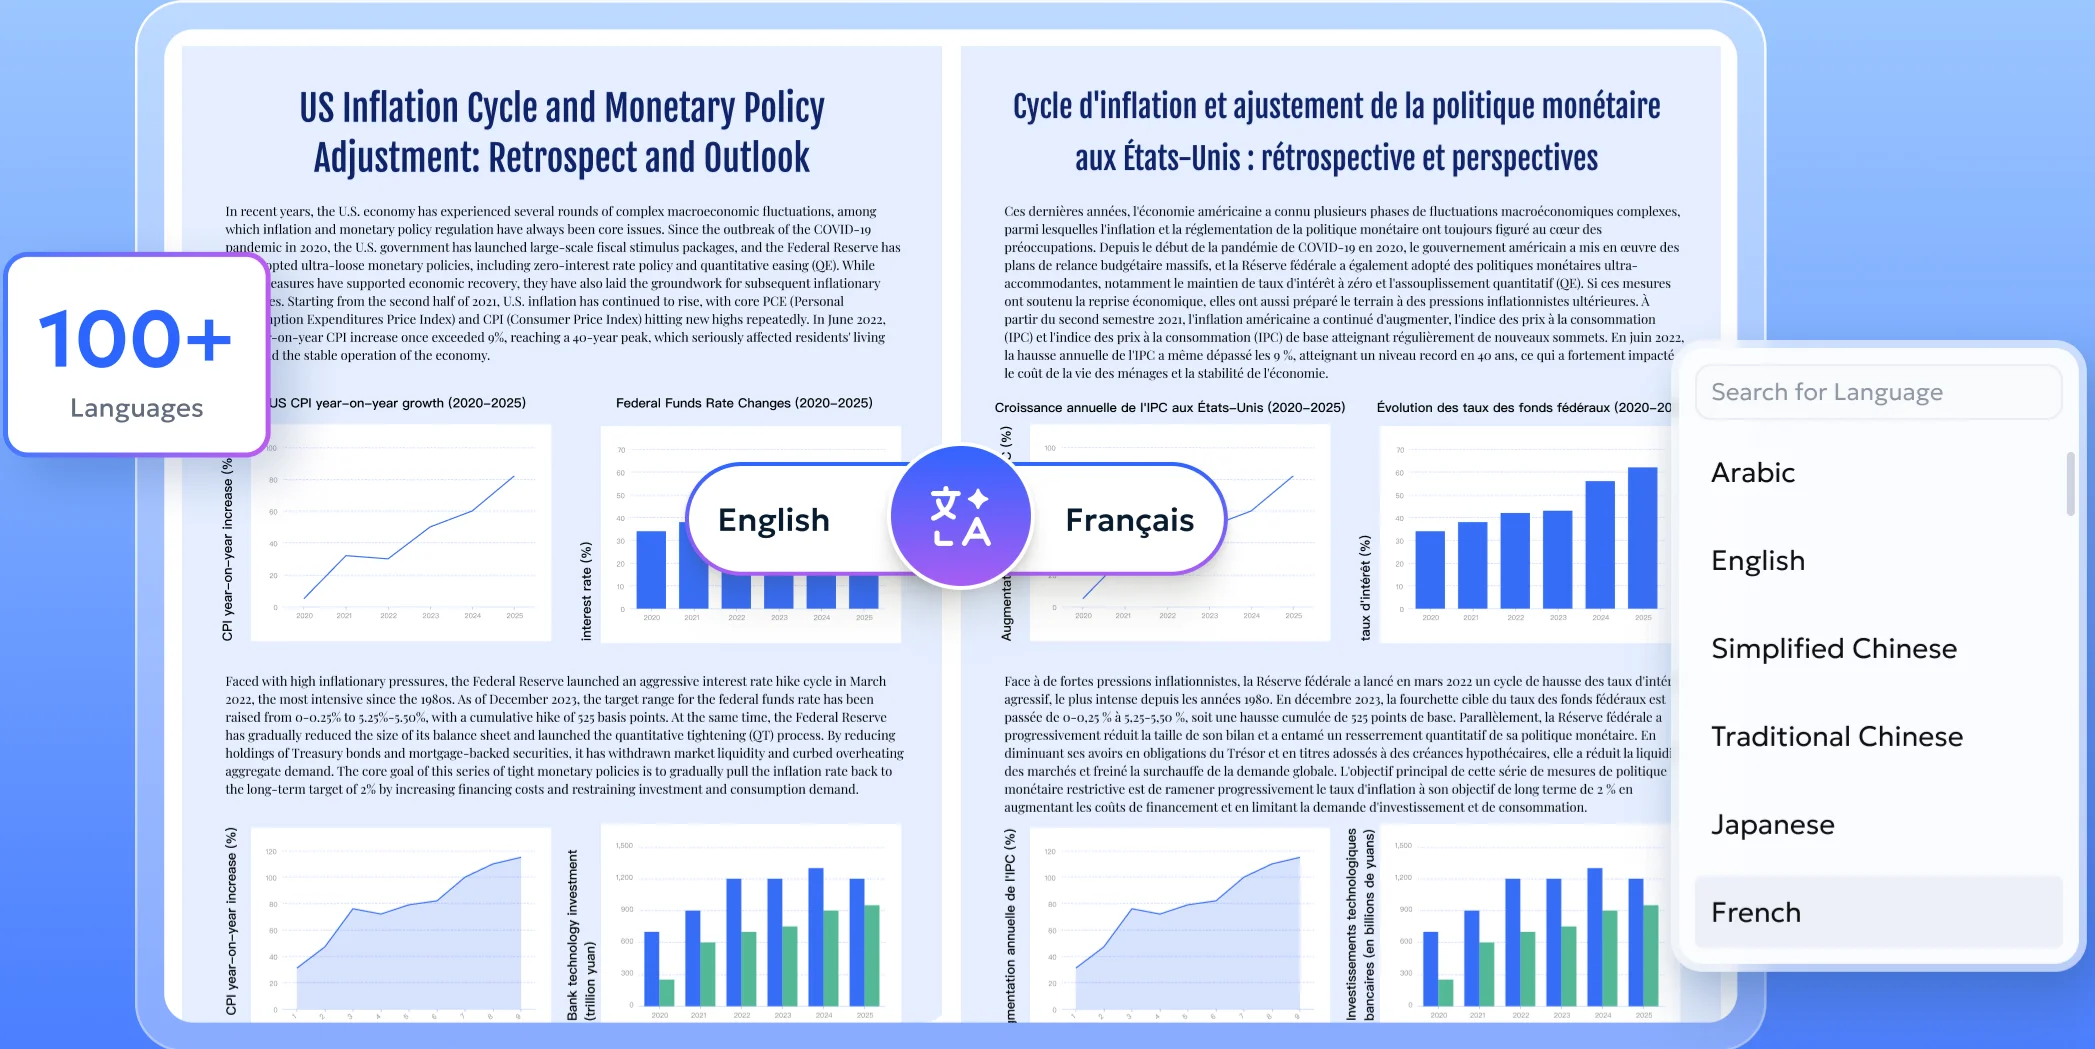
To save this time-consuming workflow, we built the in-reader bilingual mode after watching researchers and reviewers lose their reading flow to five browser tabs. We keep the source and the translation in the same window. The original sits on one side, the translation on the other, and the matching segments highlight as you move between them. You stay inside the PDF.
- Bilingual View: Original text and translated text are visible at the same time, paragraph by paragraph.
- Dynamic Translation Updates: The translation panel refreshes as you scroll through the document.
- Hover-to-Highlight: Hover on either side to highlight the matching segment in the other.
- No Tab Switching: Translation runs inside the PDF reader --- no second app, no copy-paste loop.


Where Translation Lives: In-Reader or In-Browser
Most editors either send you to a separate translation tool or offer no bilingual view at all. UPDF has a web version that supports side-by-side translation. PDFelement, Foxit, and WPS generally do not. PDNob now can offer you translation that lives next to the source text, with no second tool required.
Please swipe to view
How It Improve Your Bilingual Reading Exprience
You can stay inside the PDF instead of repeatedly copying and pasting text into another application. This is useful when:
- Reading English-language research papers and journal articles alongside translations
- Working through foreign-language technical manuals and datasheets
- Reviewing translated contracts and legal documents for accuracy
- Comparing original and translated marketing copy during localization reviews
Layout-Aware Full-Document Translation

Why Machine Translation Often Breaks the Page Layout
This may happen when you run a German manual through a machine translator. The English comes back readable, but every page now overflows the right margin --- the translated text is longer than the original, so the layout breaks. Tables stretch, headers wrap onto two lines, and the document looks like a draft.
How We Made Full-Document Translation Layout-Aware
We rebuilt full-document translation as a per-text-block decision because most translators leave German manuals overflowing past the page edge. Full-document translation almost always changes the length of the text --- German runs longer than English, Chinese shorter, French somewhere in between. Most PDF translators drop the new text into the original layout at the original font size and let it overflow. We now measure the translated sentence length per text block and adapt the font so the page stays readable without manual tweaks.
The result should still feel like the same document --- just in another language. For users translating technical documentation, academic papers, training materials, or business documents, preserving the document's structure can be just as important as getting the translation itself right.
- Adaptive Font Scaling: Font size adjusts to match the length of each translated segment.
- Block-Level Layout Preservation: Text stays inside the original paragraph and column boundaries.
- Readable Output: Translated pages keep visual balance --- no overflow, no awkward gaps.
How Each Translator Treats the Original Layout
Different translators handle layout preservation differently. WPS keeps word-level style but can struggle with complex formats. PDFelement retains basic styles with coarser restoration. Foxit focuses on speed and accuracy on simpler documents. PDNob now can offer you translation that treats layout preservation as a per-text-block decision.
Please swipe to view
Where You Feel the Difference
The goal of this design is to preserve paragraph structure, column boundaries, page layout, tables, headers and footers, and overall readability. This is useful when:
- Translating user manuals and technical specifications while preserving readability
- Translating academic papers into a second language without breaking equations or figures
- Producing bilingual versions of training materials and onboarding documents with complex layout
Part 4. Read Large and Complex PDFs Without the Wait
Two rendering capabilities of the reading feature of PDNob shape how a PDF feels when you open it: progressive loading for speed, and broad format compatibility for the messy files.
Faster Document Rendering

Waiting 20 Seconds for a 500-Page PDF Feels Lengthy
In traditional PDF editors, if you double-click a 500-page product manual, you will possibly need to watch a white screen for 15 to 20 seconds before the first page appears. By the time it loads, you have lost the thread of what you opened it for. Opening a document should not feel like waiting for a database.
How We Cut Open Time With Progressive Rendering
To cut the time you wait, we built progressive rendering because waiting 20 seconds for a 500-page PDF to open is not acceptable. We use progressive rendering --- the first screen of content appears immediately, while the rest of the document streams in the background. Large manuals, design files, and image-heavy documents of 500 pages can open in seconds, with the first screen visible before the full document finishes parsing.
In a test across five tools on cold-start performance, PDNob came in at 0.25 seconds --- the fastest of the five tested --- and used roughly 66% less memory than UPDF and PDFelement on the same workload.
- Progressive Rendering: The first screen appears before the full document is parsed.
- Faster Open Times: Large documents open in seconds rather than tens of seconds.
- Reduced White-Screen Wait: Users see content the moment they hit Open.
What Slows Down a 500-Page Open
Cold-start speed and large-document handling vary across editors. Foxit and PDFelement generally handle standard documents well but slow down on the complex ones. UPDF, in our test, was the slowest on complex documents. PDNob now can offer you first-screen rendering and roughly 66% lower memory use than UPDF and PDFelement on complex workloads.
Please swipe to view
Where PDNob Cut the Waiting Time
For a 500-page document, we only hope the progressive loading can let you start reading as quickly as possible. This is useful when:
- Opening multi-hundred-page research papers, theses, and reports without delay
- Loading technical manuals and product datasheets for quick reference
- Reviewing image-heavy design drafts and brochures
- Working with scanned document compilations that span hundreds of pages
Stronger Rendering Compatibility
Why Some PDFs Refuse to Open in Most Readers
If you open a CAD export saved as PDF in your usual reader and see errors, a blank page, or a missing image. The file is fine in one reader but broken in others --- because some PDFs come from specialized design tools, have been edited and re-exported many times, or simply do not strictly follow the PDF specification.
How We Handled Non-Standard PDFs
We tested extensively against non-standard PDFs because opening a CAD export that errors out can be one of the most frustrating moments. We designed the rendering pipeline to handle a broad range of PDF structures --- complex vector graphics, paths and shapes, clipping, layers, transparency and masks, and PDFs that do not strictly follow the expected structures. Where a typical reader might error out, we try to render what is there.
This matters most for CAD exports, engineering drawings, design files, and documents that have been through multiple rounds of editing and re-export.
- Vector Graphics Support: Handles complex paths, shapes, and clipping precisely.
- Layer and Mask Compatibility: Supports multi-channel layers and transparency masks.
- Graceful Degradation: Non-standard files render instead of erroring out.
What Happens to Non-Standard PDFs in Other Readers
Compatibility with non-standard PDFs tends to be where editors diverge. In our testing, Foxit, PDFelement, and UPDF each showed errors or blank pages on some non-standard PDFs. PDNob now can offer you graceful rendering of non-standard PDFs that other readers may reject.
Please swipe to view
Where It Slots Into Your Reading Experience
You do not need to understand any of those underlying structures. They simply need the document to open and display correctly. This is useful when:
- Opening CAD exports and engineering drawings saved as PDF
- Reading PDFs produced by specialized design or publishing software
- Loading PDFs that have been through multiple round-trips of editing and re-export
Part 5. Annotate PDFs Without Losing Track of Your Edits
Two PDNob annotation feature behaviors keep markup useful through every revision pass --- annotations that follow text edits, and one-click hide when you need a clean view.
Annotations That Follow Text Edits
Why Highlights Should Move With the Text You Edit
It can be troublesome without this design seeming minor. If you highlight a key clause in a contract, then later edit the wording above it. You come back and the highlight is still anchored to the old position --- no longer covering the words it was meant to flag. After a few revision passes, your markup is detached from the text it was supposed to mark.
How We Bound Annotations to the Text
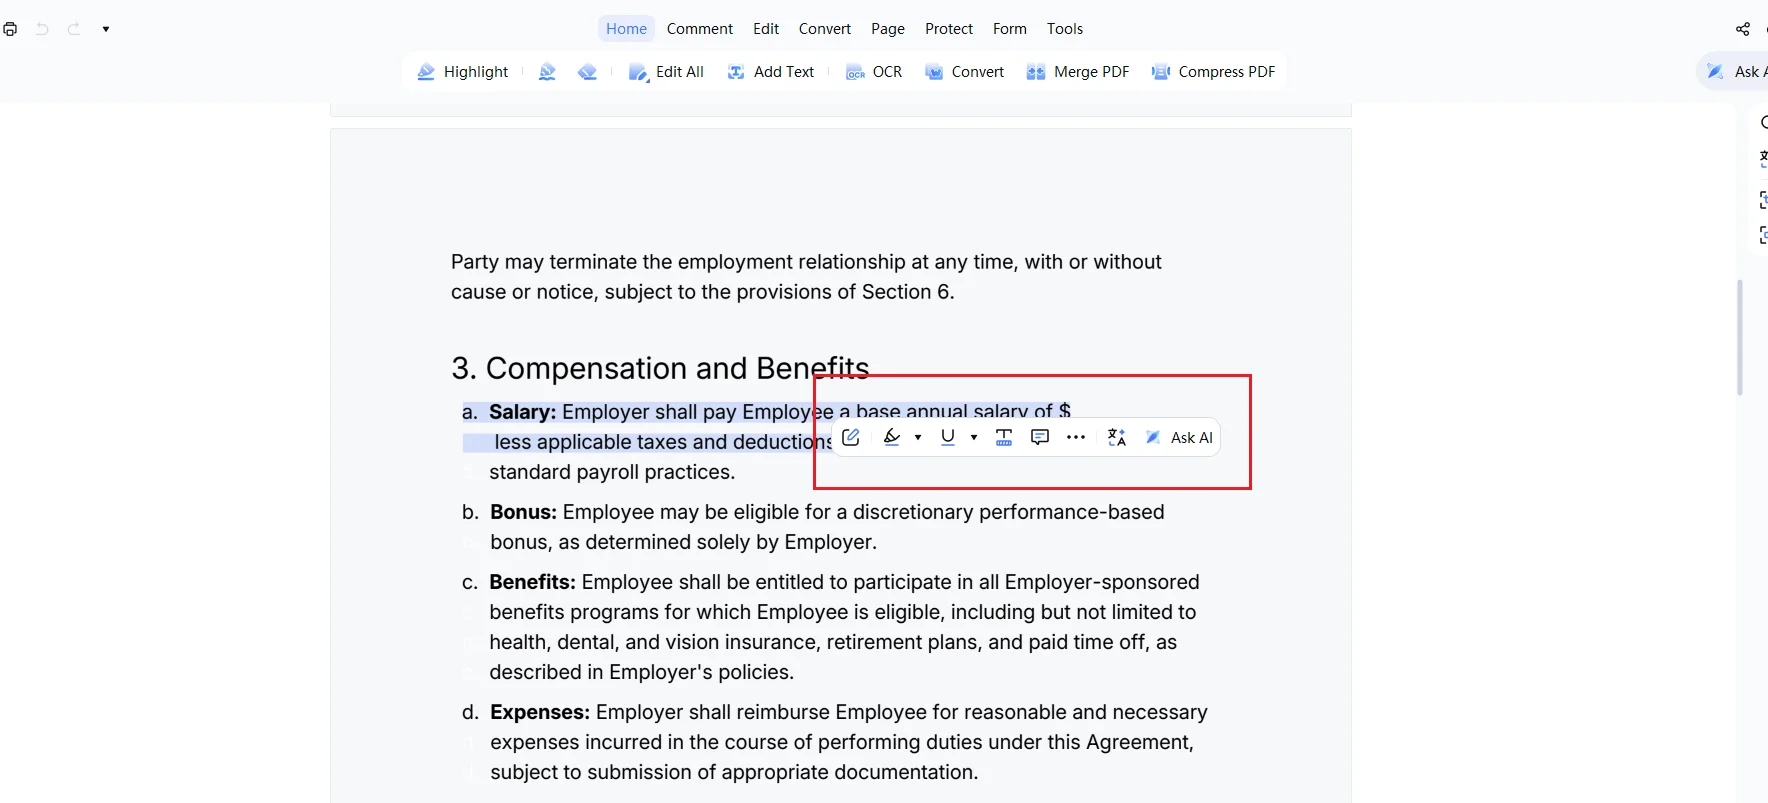
We rebuilt annotation binding after watching legal and editorial teams redo the same markup after every revision pass. We keep annotations bound to the text they reference. Highlights, underlines, strikethroughs, and wavy underlines follow the words through edits. Comments stay attached to the relevant text segments.
- Highlight Persistence: Highlights, underlines, strikethroughs, and wavy underlines move with the underlying text.
- No Manual Re-annotation: Avoid redoing markup after every revision pass.
- Comment Tracking: Comments stay attached to their referenced text segments.
- Marking up contracts during initial review and keeping the markup intact through revisions
- Highlighting key sentences in research papers and editing those sentences without losing marks
- Reviewing draft reports where copy edits happen alongside annotation passes
- One-Click Toggle: Show or hide all annotations instantly.
- Annotation Preservation: Hiding does not delete --- annotations stay attached to the document.
- Distraction-Free Reading: View a clean version for review or printing.
- Reviewing a paper covered in supervisor comments without the markup getting in the way
- Checking the final visual flow of a redlined contract before signing
-
Direct Tool Invocation: AI calls OCR, format conversion, compression, and other PDF tools on demand.
-
Natural Language Trigger: Users describe what they need in plain language.
-
Returned Output: AI returns the result file directly, ready to use.
- Converting a PDF to Word or Excel by describing the task in one sentence
- Chaining multiple operations --- convert, compress, rename --- through a single conversation
- Make scanned PDFs searchable and editable with 99% OCR precision
- Batch convert PDFs to Word, Excel, PPT, images, PDF/A, Text, EPUB, etc., up to 30% faster
- Edit PDFs easily like Word, including text, images, watermarks, links, and backgrounds
- Annotate PDF with highlights, comments, shapes, stickers, and stamps
- Run smoothly on any PC without lags or crashes, even on low-spec machines

Where Annotations Lose Their Reference
Annotation tracking is one of the areas where editors split. Adobe supports it. PDFelement, Foxit, UPDF, and WPS generally treat annotations as fixed positions on the page, which means they lose their reference after text edits. PDNob now can offer you annotations that follow the underlying text through edits.
Please swipe to view
Where You See the Difference
Instead of repeatedly recreating annotations after every text change, you can continue working with the same markup. This can help during contract review, academic editing, report revision, document proofreading, and collaborative review workflows. This is useful when:
One-Click Hide All Annotations

When You Need to Hide Annotations Rather Than Deleting Them
Let's say you are about to send the final draft of a contract. The page is covered in yellow highlights, red underlines, and margin comments from the review pass. You want to see the document cleanly --- but you do not want to delete any of the work. This is what this design is built for.
How We Built the One-Click Hide Toggle
We built the one-click hide toggle because hiding markup should not mean deleting your work. We let you hide every annotation with one click. Nothing is deleted; the annotations stay attached to the document. Another click brings them back. This lets you switch between review mode (with markup) and clean reading mode (without visual clutter) without losing anything.
What Hiding Markup Actually Does to Your Work
Hide-on-demand is supported in some form by Foxit, PDFelement, and others, but the way hiding is implemented differs --- some tools delete markup in certain views. PDNob now can offer you a hide toggle that preserves every annotation through the toggle.
Please swipe to view
Where It Pays Off
The annotations remain in the document and can be shown again later. This makes it easier to switch between review mode and clean reading mode. It can be useful when reviewing a final contract, checking the visual appearance of a report, or preparing a document for printing. This is useful when:
Part 6. Let AI Handle PDF Tasks with Natural Language

Why AI Should Do the Work, Not Just Talk About It
"Convert this PDF to Word" should be one sentence away. In most PDF tools, it is a menu, then a format picker, then an output location, then a dialog to confirm. Other AI assistants can answer the question but still expect you to do the work yourself --- the assistant opens a dialog and waits for you to click.
How We Built Direct Tool Invocation
We built direct tool invocation because describing a task should be the entire job --- not a step before opening a dialog and clicking again. The AI assistant can call PDF tools directly --- OCR, format conversion, compression --- execute the operation, and return the resulting file. You describe what you need in plain language; the AI triggers the appropriate PDF operation and hands back the result.
The important distinction is that the AI is not replacing the underlying PDF engine --- AI provides a more natural interface, and the PDF tools still perform the actual work. The result is one-sentence tasks instead of five-step workflows, and chained workflows become a single conversation.
Where the AI Stops and Hands the Work Back
Different AI assistants handle the same task in different ways. Foxit and Adobe support AI-driven tool use, though the depth of execution varies. UPDF's assistant can open the right dialog but still expects you to confirm. PDFelement currently does not offer this kind of invocation. PDNob now can offer you an AI that calls the PDF tool directly and returns the file --- no second confirmation click.
Please swipe to view
How It Helps Your Workflow
This can particularly save your time when several mechanical operations need to be combined. This is useful when:
Final Words
Across the six areas covered here --- OCR pre-processing, reading-mode editing, translation, large-document rendering, annotation tracking, and AI tool calling --- we kept returning to the same question: where does a hard PDF break first, and how much of that break can we prevent quietly, before it happens. The choices behind each area are easy to miss,and we built them without users having to notice them so as to make the workflow silky.
PDF software is easy to judge by its feature list. But when you work with a difficult document, the experience is often determined by much smaller things. For us, building a better PDF product is not just about adding more features. It is about getting the details right.
Frequently Asked Questions on PDNob Advanced Features
Q1. Does PDNob run on both Windows and Mac?
A1: Yes. PDNob is available on Windows and macOS with the same feature set on both platforms.
Q2. Do I need to switch to edit mode to change a word in a PDF?
A2: No. In PDNob, click any text in reading view and start typing --- the cursor appears where you click and the original font, size, bold, and italic are preserved.
Q3. Do I have to run all five OCR pre-processing passes every time?
A3: No. Each pass --- auto crop, deskew, contrast enhancement, speckle removal, and denoise --- can be turned on or off independently from the OCR settings, so you can match the engine to the document.
Q4. Does bilingual translation keep the original layout intact?
A4: Yes. Tables, headers, footers, and fonts stay in place. The engine runs on the text layer rather than a flattened image, and font scaling adapts to keep translated content within the original layout. A translated contract looks identical to the original except for the language. Standard business documents pass through cleanly.
Q5. Can annotation tracking work across a team?
A5: Yes. PDNob Cloud tracks every comment, highlight, and revision with author, timestamp, and resolved status. Reviewers reply in threads, mark items resolved, and filter to open items.


 Secure Download
Speak Your Mind
then write your review
Speak Your Mind
Leave a Comment
Create your review for PDNob articles
Related articles
AI Tools Writer / Workflow Analyst
Rachel has spent the last 5 years testing and writing about AI-powered tools across writing, design, and research workflows. She focuses on practical AI tool usage, helping knowledge workers turn generative AI into everyday productivity.